"We cut our pipeline delivery time from 6 weeks to 3 days. The observability layer alone caught 40+ silent failures in the first month. Absolute game-changer."
Priya SharmaHead of Data · FinFlow
Data Work Project is the modern platform for teams who build with data. Ingest, transform, observe, and deploy — all in one unified workspace. No glue code. No vendor sprawl.
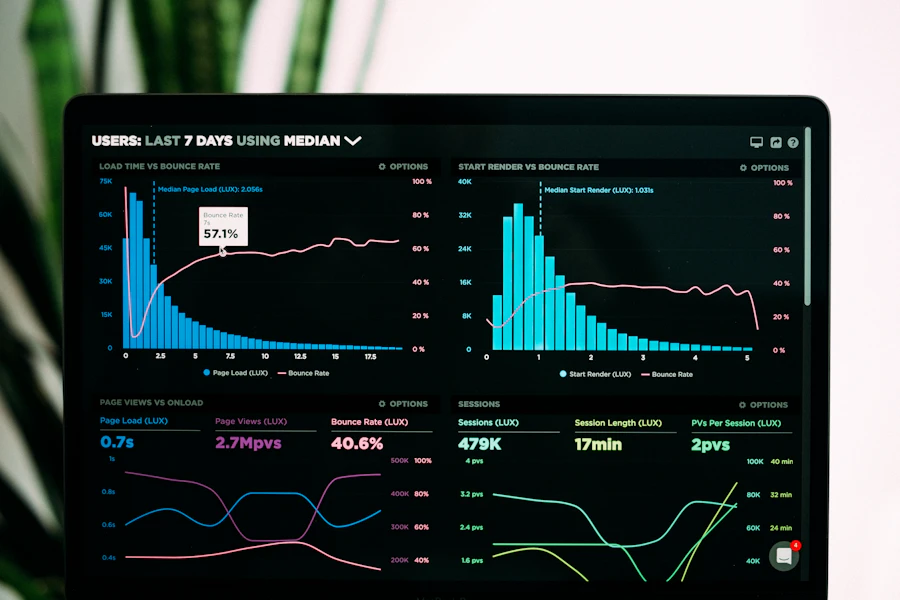
From event ingestion to production ML — composable primitives that just work together.
Stream millions of events per second with sub-second latency. Native connectors for Kafka, Kinesis, Pub/Sub, and 200+ sources.
SOC 2 Type II, HIPAA, GDPR. SSO, RBAC, full audit trails.
Vector stores, feature stores, and model registries — ready on day one.
Every job, every model, every pipeline — monitored in real time.
Auto-scaling compute that adapts to your workload. Scale to zero when idle.
Connect, transform, monitor, deploy — all from one interface.
Plug in databases, APIs, event streams and SaaS tools with 200+ pre-built connectors.
Use SQL, Python or a visual builder to clean, join and model data at any scale.
Track data quality, pipeline health and model drift with real-time dashboards.
Expose clean data via APIs, dashboards or AI apps — backed by auto-scaling infrastructure.
Whether you're a two-person startup or a Fortune 500, Data Work Project scales with you.
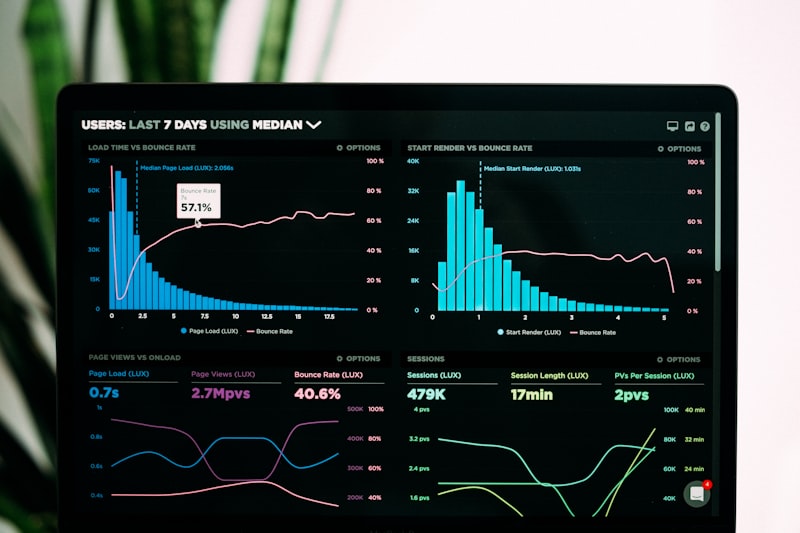
Self-serve analytics for product and business teams. Query billions of rows in seconds with zero tuning.

Build and monitor production-grade data pipelines with built-in lineage, testing and versioning.
Train, deploy and monitor ML models at scale. Native LLM and vector search support for modern AI apps.
Real results from teams building on Data Work Project.
"We cut our pipeline delivery time from 6 weeks to 3 days. The observability layer alone caught 40+ silent failures in the first month. Absolute game-changer."
"We process 240K events per second through Data Work Project. The auto-scaling is flawless — we've never hit a bottleneck, even during peak Black Friday traffic."
"The AI/ML tooling is second to none. We deployed our first LLM-powered feature in two days using their vector store and model registry. Our data scientists love it."
Most teams are up and running within 15 minutes. Connect your first data source, write a transform, and deploy a pipeline — all from our web interface. No infrastructure to provision, no software to install.
We support 200+ connectors including PostgreSQL, MySQL, MongoDB, Snowflake, BigQuery, Redshift, Kafka, Kinesis, S3, GCS, Salesforce, HubSpot, and generic REST/GraphQL APIs. Custom connectors can be built with our SDK.
We offer usage-based pricing starting free for small teams. You pay for compute and storage consumed — no per-seat charges. Volume discounts kick in automatically as you scale. Enterprise plans include dedicated support and custom SLAs.
Absolutely. We are SOC 2 Type II certified, HIPAA and GDPR compliant. All data is encrypted in transit (TLS 1.3) and at rest (AES-256). We offer private VPC deployment, RBAC, SSO/SAML, and full audit logging.
Yes — our Model Ops suite supports training, versioning, deployment, and monitoring of ML models. We natively support LLMs, vector databases, feature stores, and popular frameworks like PyTorch, TensorFlow and scikit-learn.
All plans include community support and documentation. Professional plans add email and chat support with 4-hour response. Enterprise plans include a dedicated Slack channel, 24/7 on-call, and quarterly business reviews.
Start building for free — no credit card required. Get full access to every feature for 14 days. Cancel anytime.